Technology

True dataflow
AI architecture

MemryX maps neural networks across distributed compute and memory, then executes them as data becomes available.

Mapped onceDriven by dataExecuted concurrently
Scroll

The model defines the flow. The compiler maps the neural network across the accelerator, and at runtime computation progresses as the data each mapped operation needs becomes available.

No central memory, no router, no instruction fetch. Producers write into the shared memory beside them, consumers start on the first quantum that lands, and the whole graph runs as one continuous pipeline.

How true dataflow works

The model defines the flow

Start with the neural network

Every trained model already describes how its data moves.

The graph names each operation and the tensors it consumes.

Producer and consumer relationships are fixed before anything runs.

None of this is MemryX-specific — it is the network you trained.
Why it matters

What true dataflow gives you

Mapped ahead of time and driven by data, the architecture pays off in four ways.

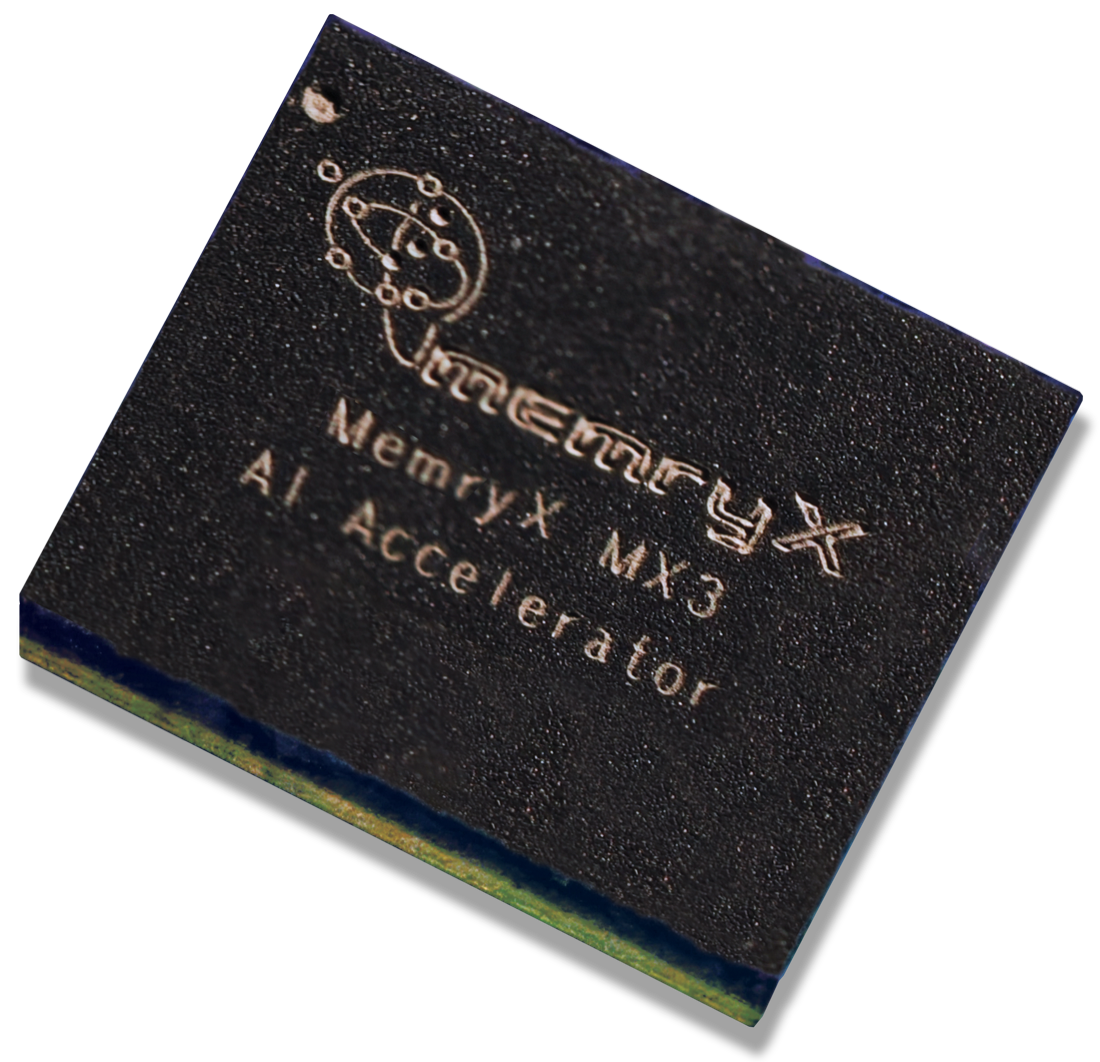
MemryX MX3 AI accelerator chip, close up Performance

Energy-efficient performance

Data stays next to the compute that uses it and more of the chip stays busy, so more work gets done for less energy.

MemryX MX3 AI accelerator die Accuracy

Maintains accuracy with BF16 inference

Feature maps stay in a floating-point format, so accuracy holds without a calibration dataset.

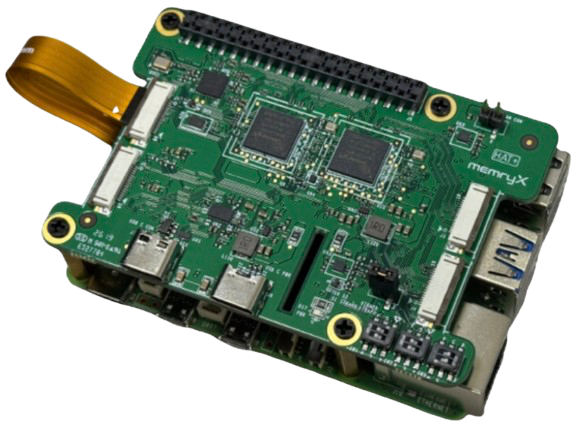
MemryX Cascade 100R accelerator board Model support

Runs a broad range of models

The compiler maps and adapts your network to the hardware, so a broad range of models runs efficiently.

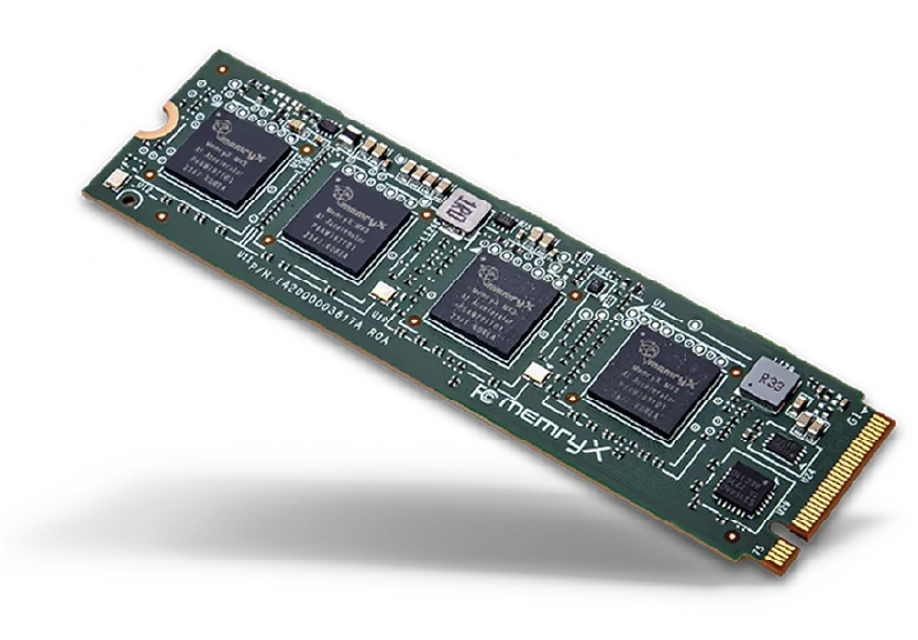
MemryX M.2 module carrying four MX3 accelerators Scalability

Start small. Scale up.

The same execution model extends from one chip to cascaded chips that act as one logical device, with no host orchestrating each stage.

What enables it

Built for dataflow from the ground up

Hardware, memory and compiler work together, so a model is mapped once and runs as a continuous, data-driven pipeline.

Mapped before it runs

The compiler places the whole graph.

Compiler

Memory inside the fabric

Data sits beside the compute that uses it.

On-chip memory

Cores that run on data

No instruction fetch, no scheduler.

Dataflow cores

Accuracy without calibration

BF16 feature maps, quantized weights.

Hybrid precision

Near-memory and at-memory compute are part of this system — an important enabler of efficient dataflow execution, not the architecture’s defining idea.

Map your model onto the fabric.

Compile a network once and run it from a 3 W module to cascaded accelerators. The toolchain is a free download.