One chip family, from a 3-watt sensor to a full server rack — on a fraction of a GPU's power.
2025 Edge AI & Vision Alliance
Product of the Year Award
Built for inference at every scale. One dataflow architecture runs from a 3 W chip at the sensor to a full rack in the data center — no rewrites, no compromises.
One toolchain from edge to cloud. Our compiler maps any model onto the fabric automatically, delivering deterministic latency and order-of-magnitude power efficiency on every request.
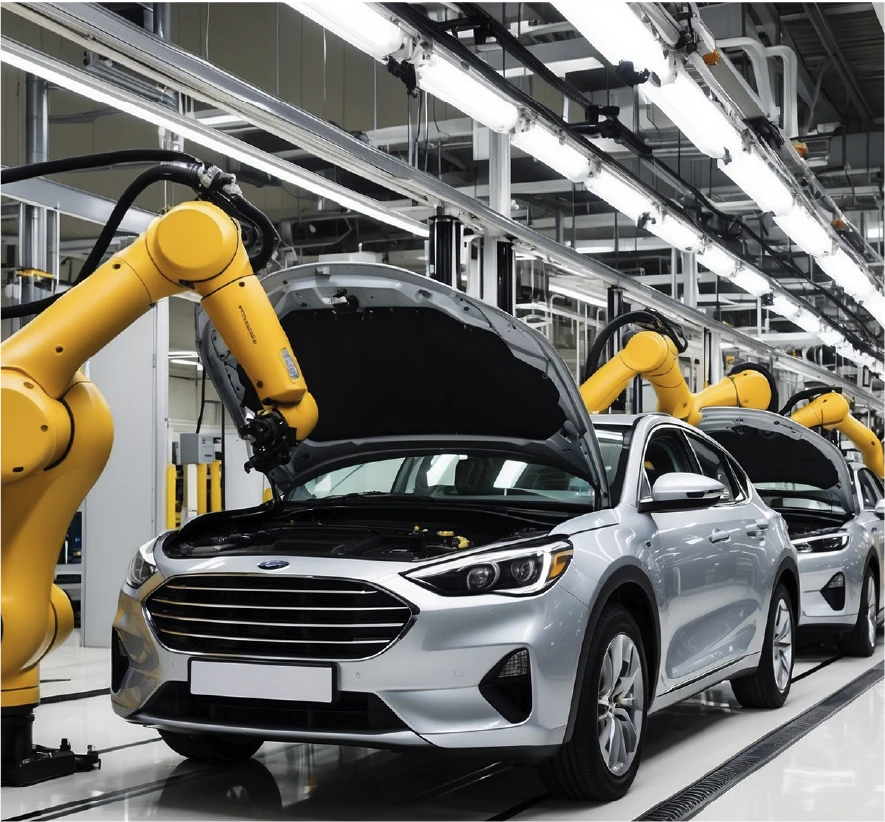
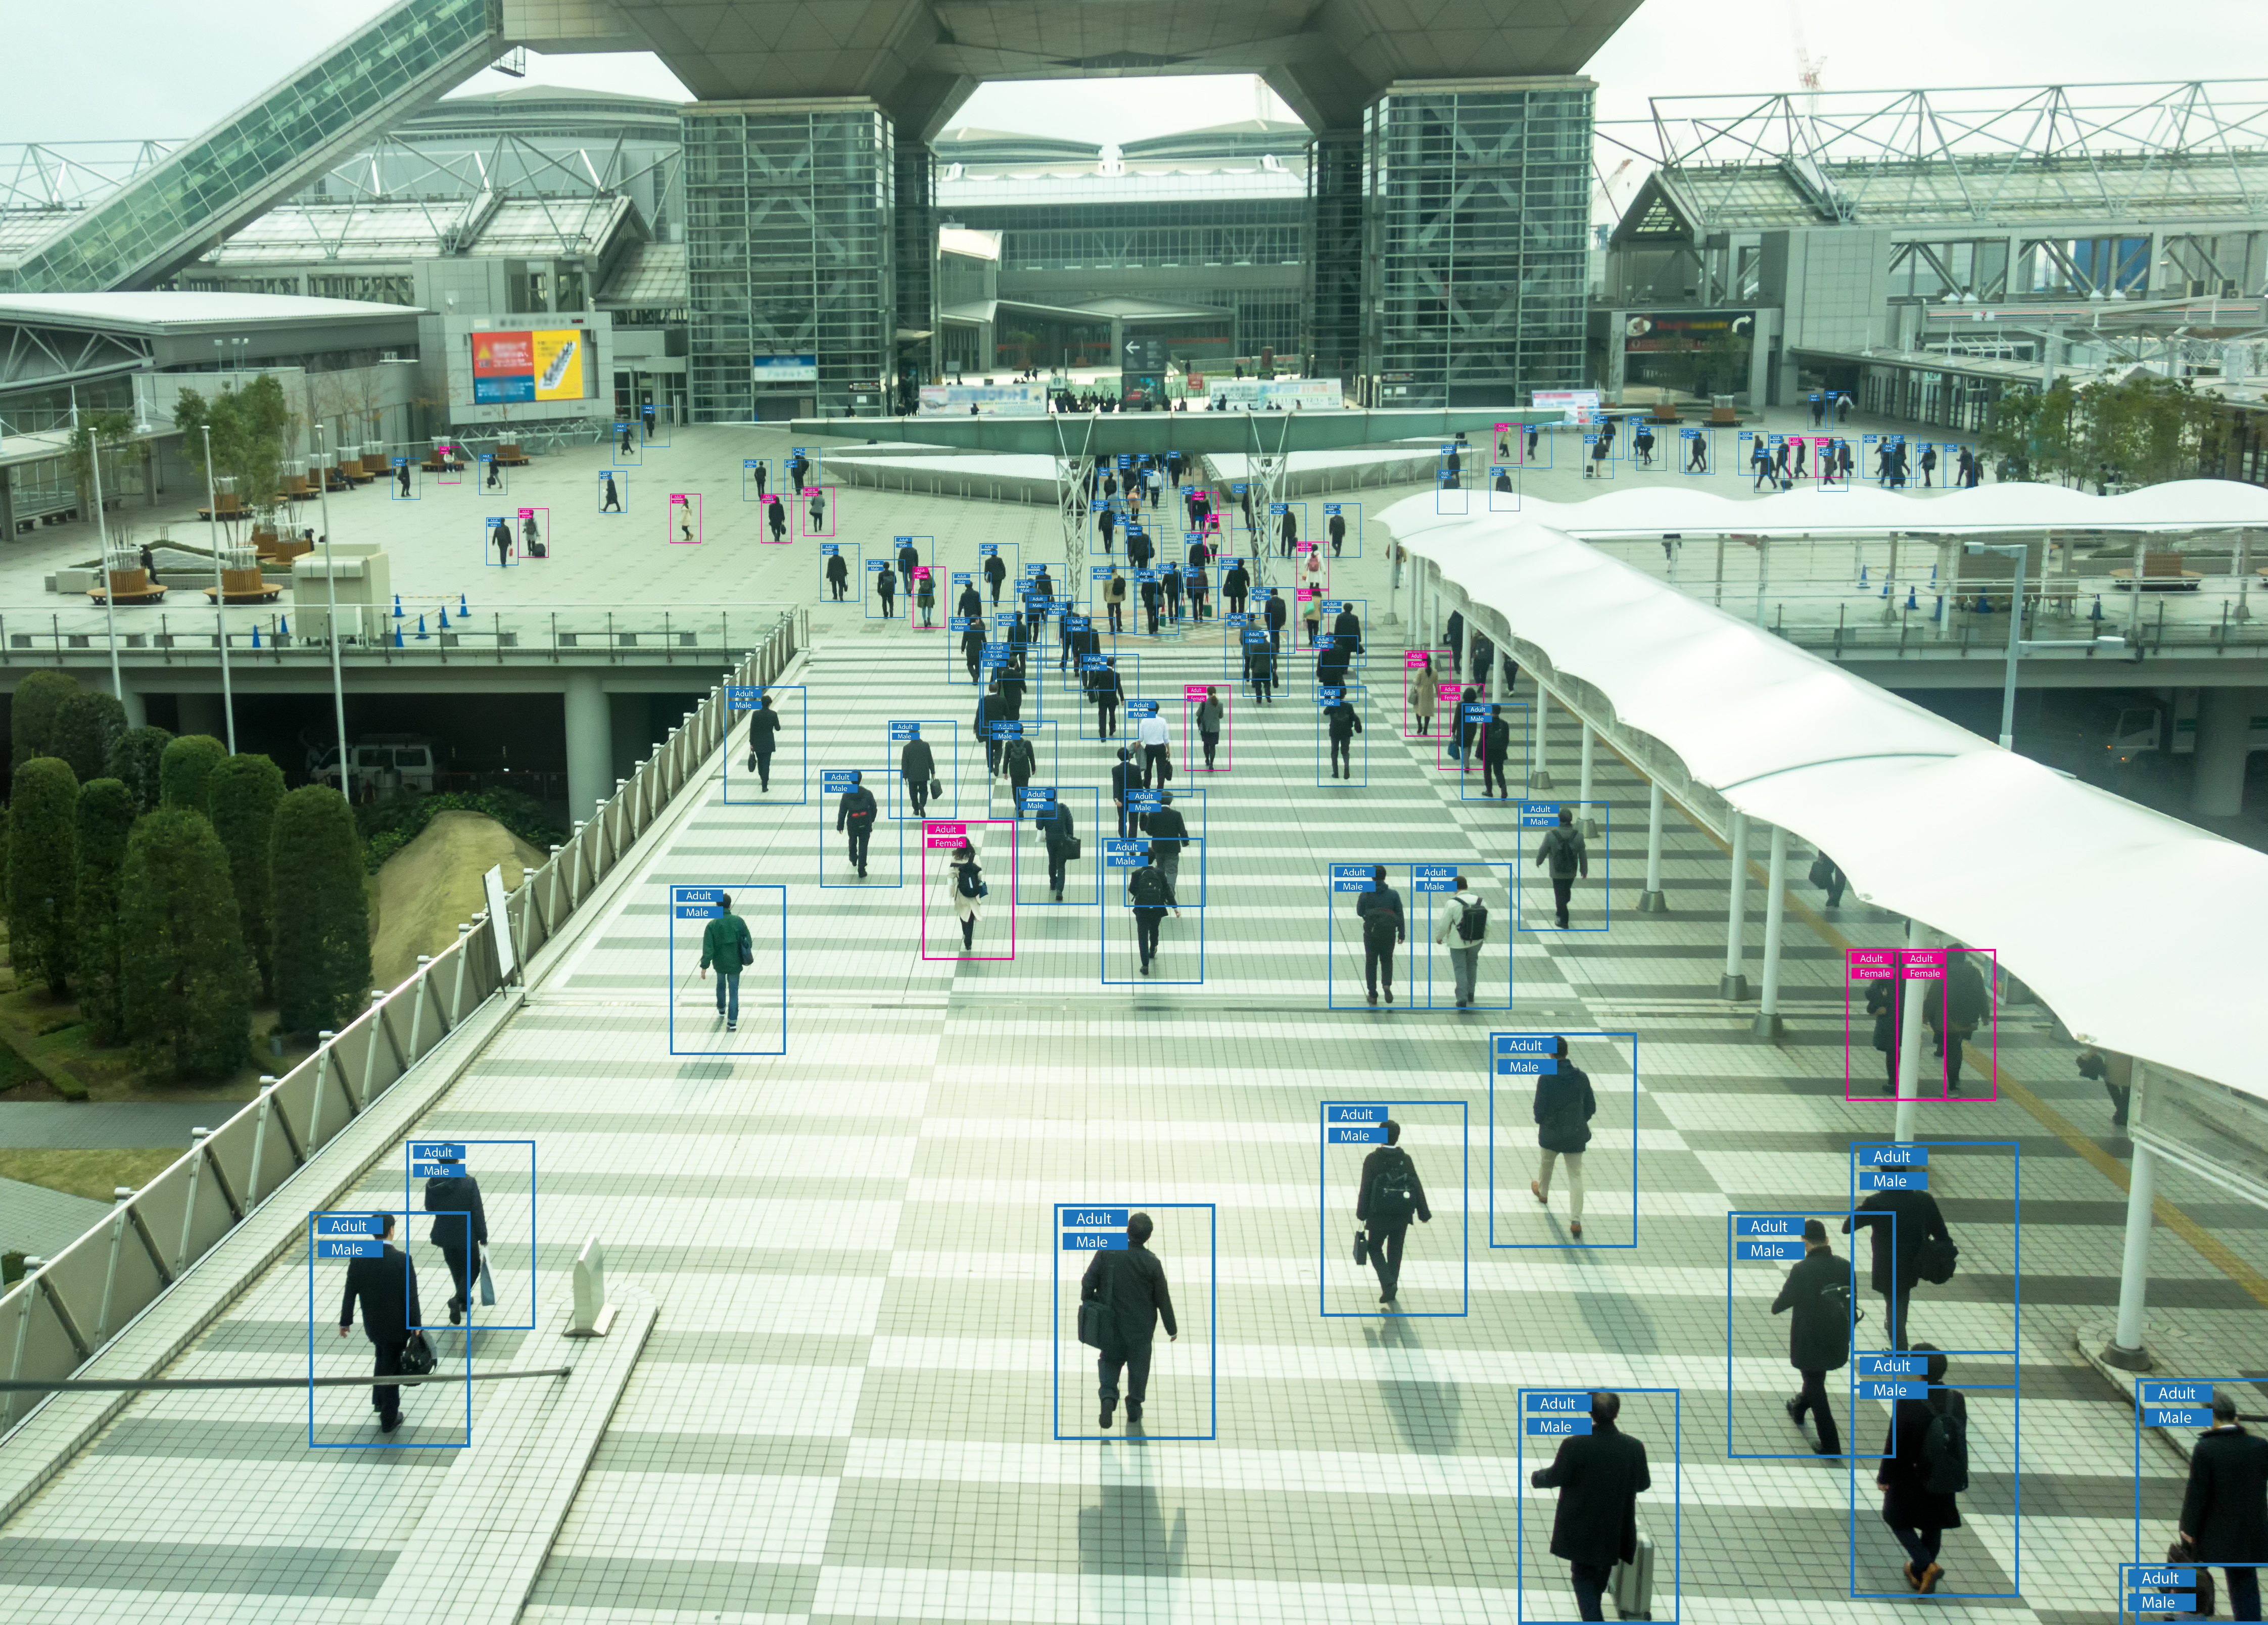
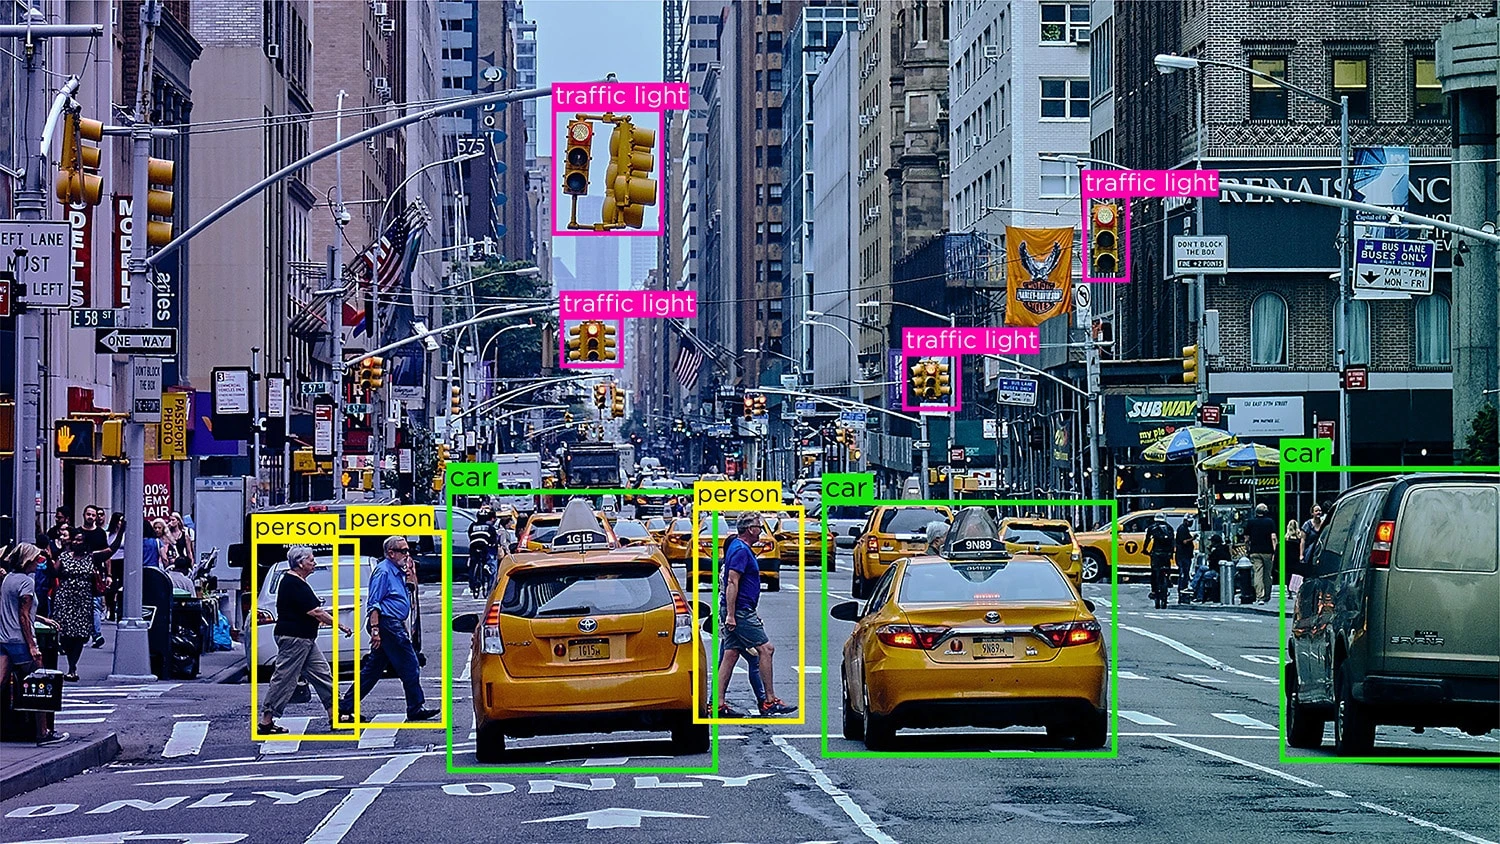
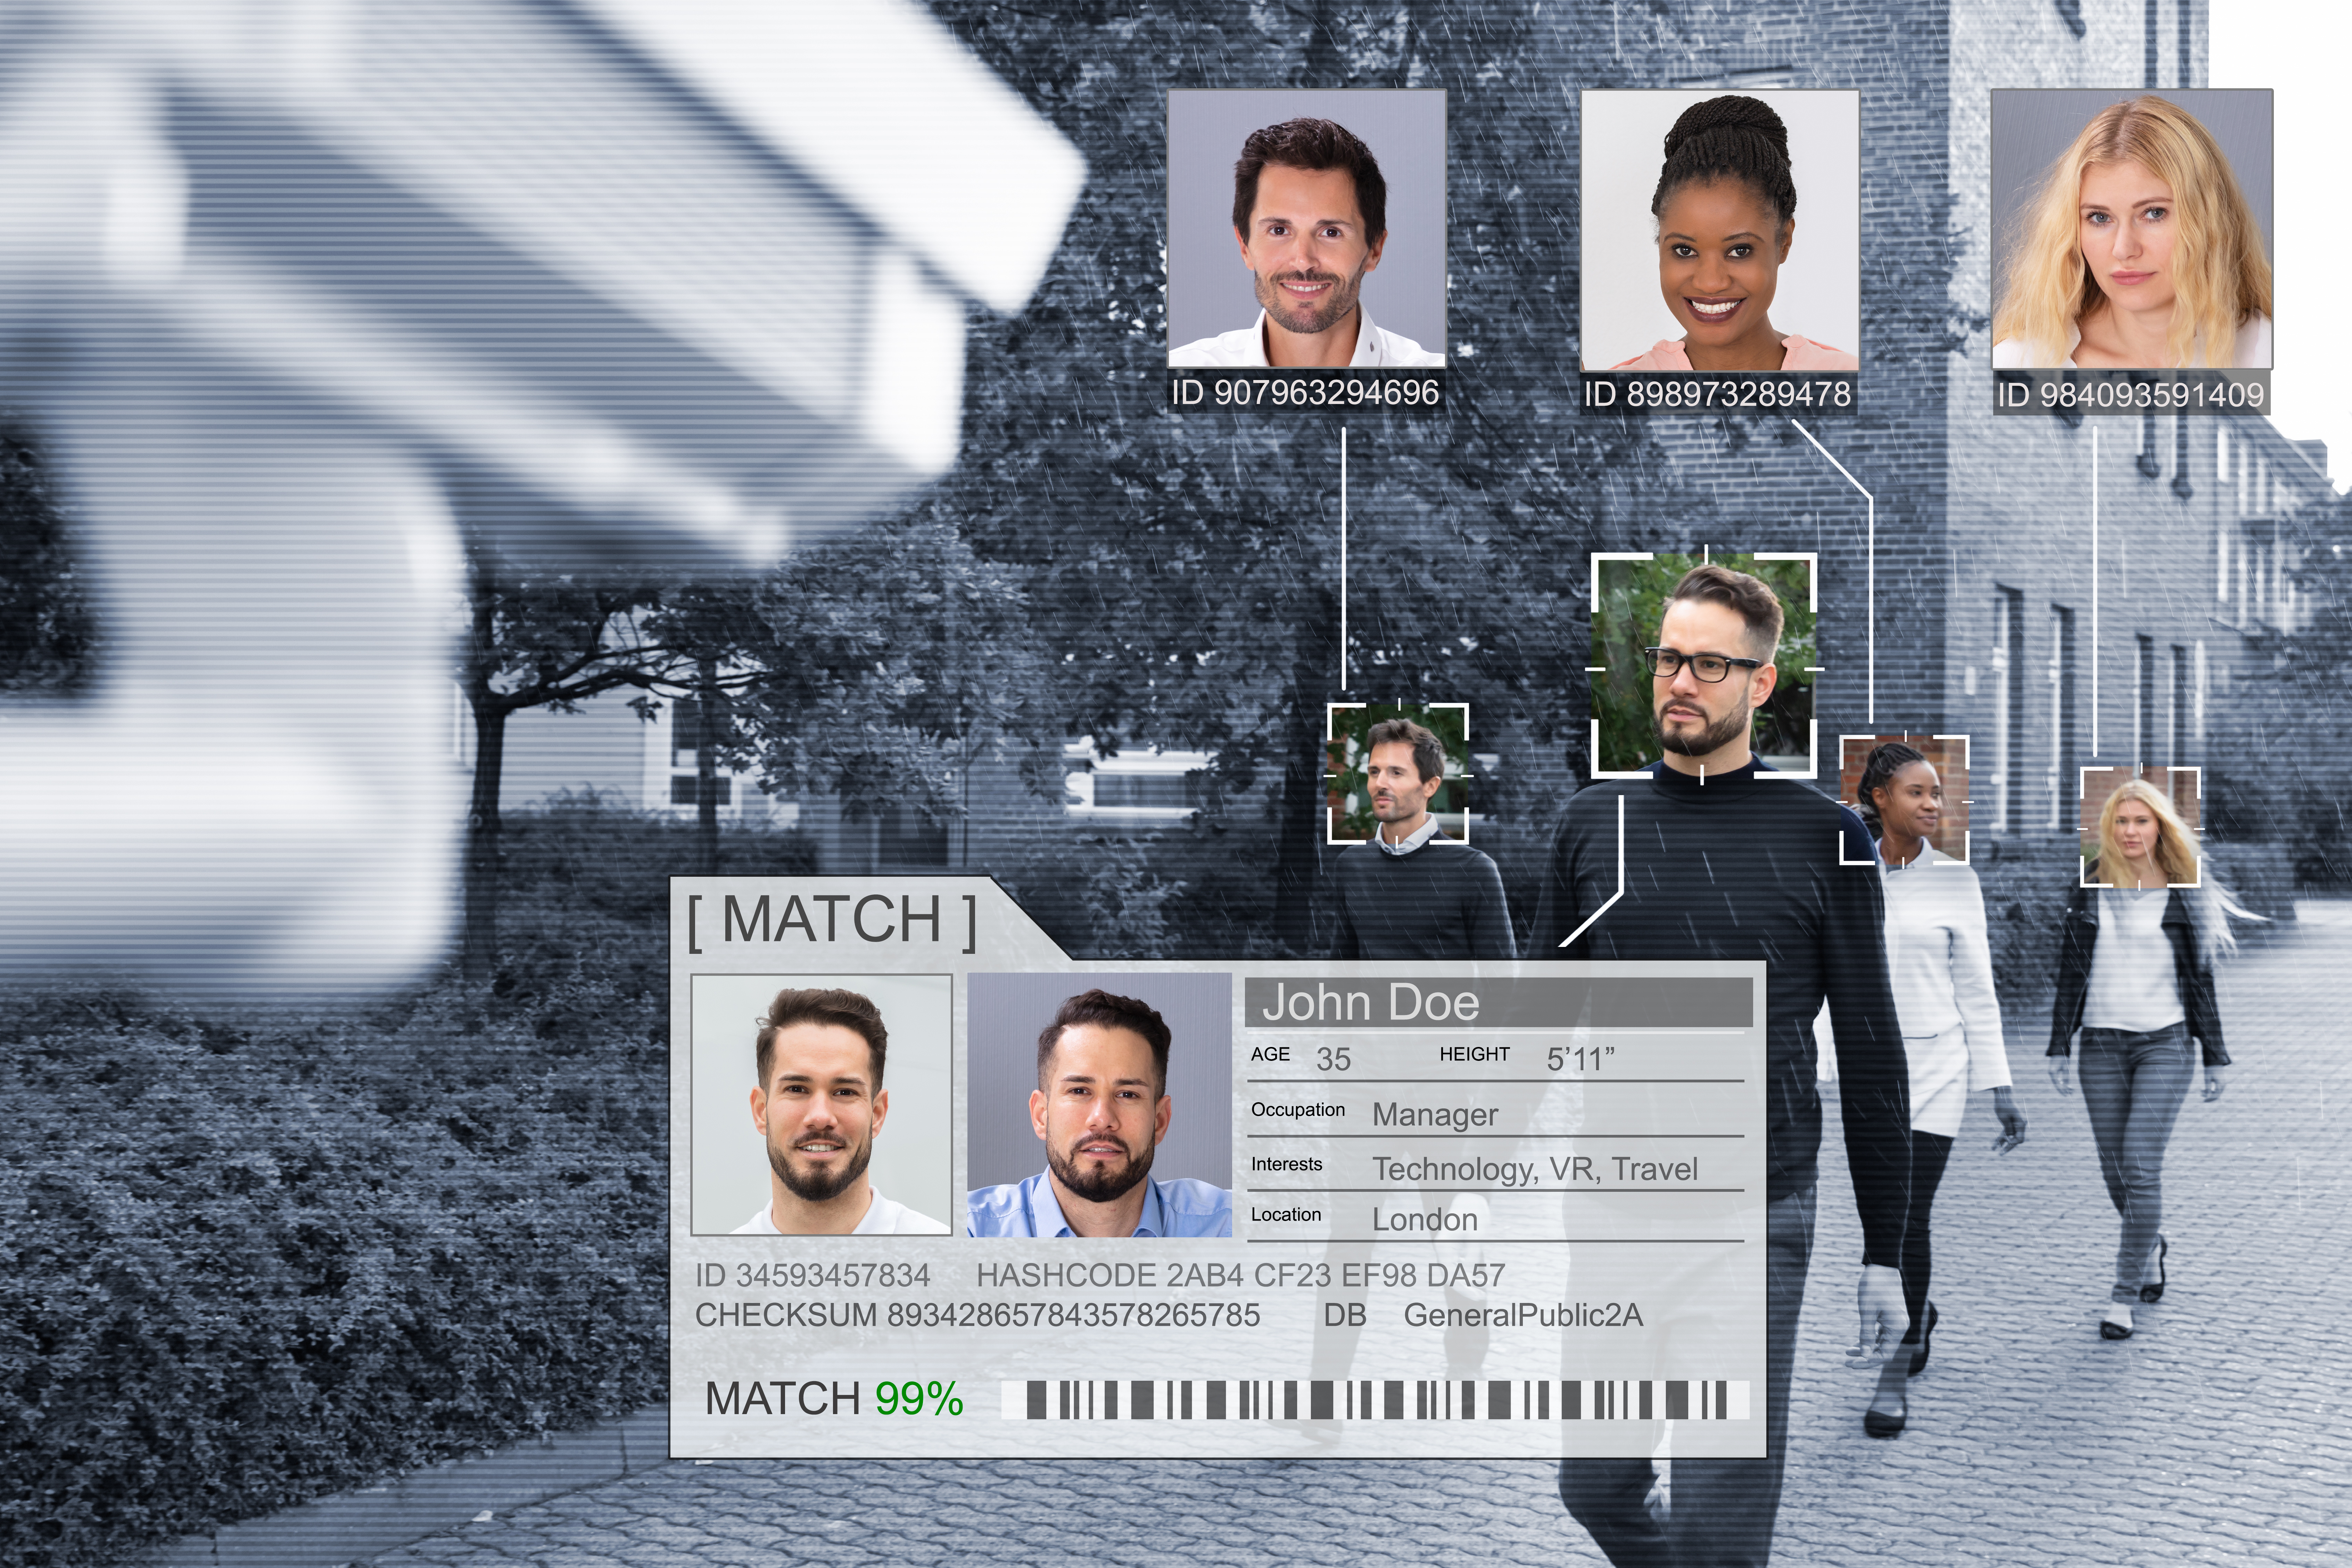
The same architecture, deployed across every environment that needs inference at the edge.
Explore solutions →Manufacturing, automation and edge computing on the factory floor.

AI-powered surveillance and smart vision at scale.

Automotive and mobility applications, from cabin to roadside.

On-device intelligence for connected edge products.

A dataflow, at-memory architecture streams data between processing elements — cutting the power-hungry memory access that limits GPUs and CPUs.
Start with the bare chip, drop in a ready-made module, or deploy a finished box — same architecture and the same toolchain, whichever you pick.
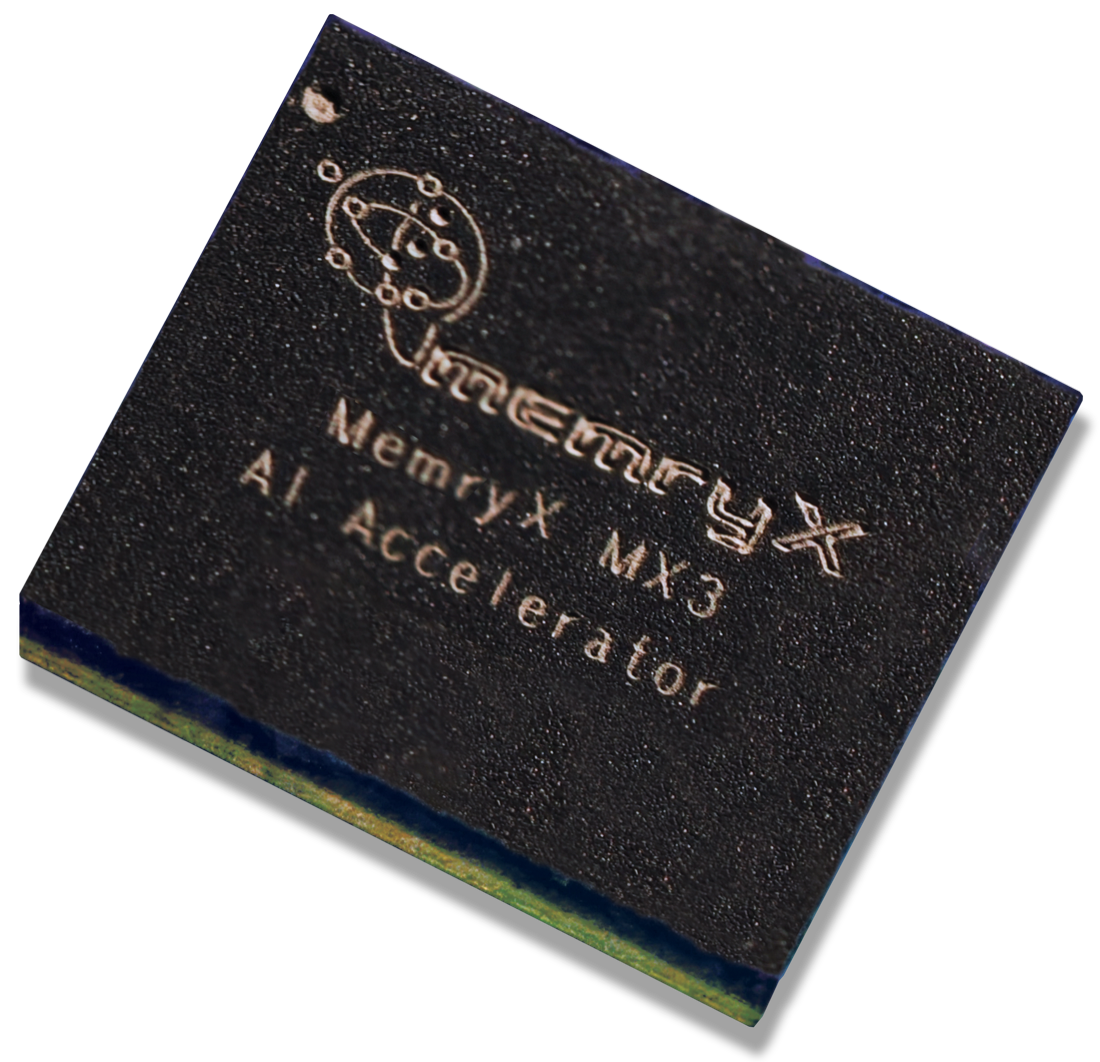
The MX3 AI accelerator — 6 TFLOPS at roughly 3 W. The dataflow core everything is built on.
Explore →
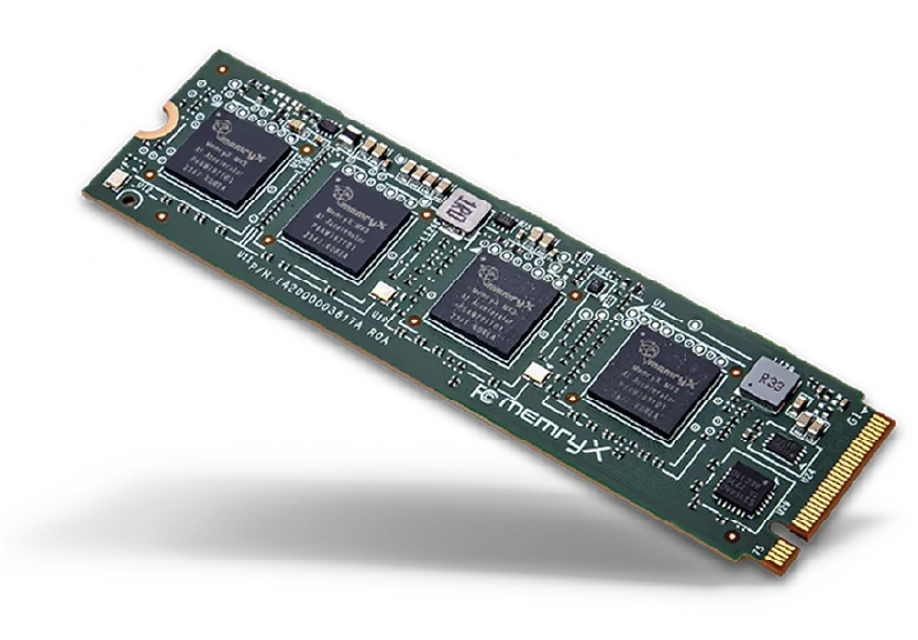
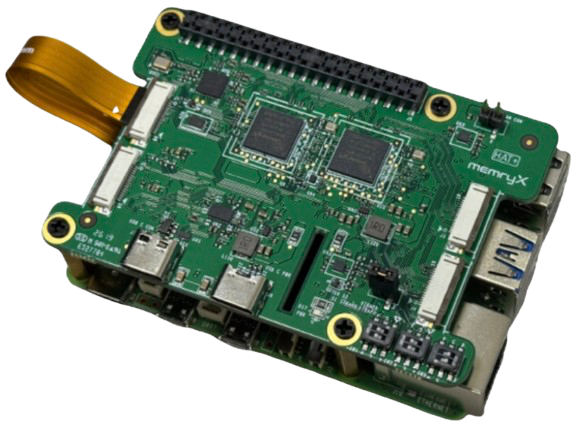
The Cascade 100 family — Raspberry Pi HAT+, USB-C, M.2 and PCIe. From 12 to 100 TFLOPS.
Explore →
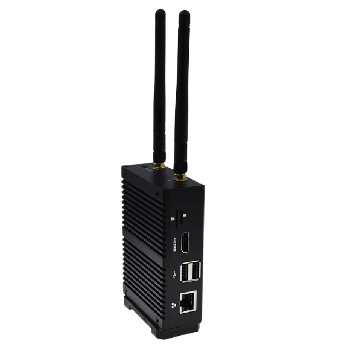
Ready-to-deploy edge and server systems for production inference at scale.
Explore →Keep what works. Accelerate what matters.
Your stack stays as it is.
More AI capability. Less disruption.
Not our claims — theirs. Five independent labs, reviewers and publications put the MX3 through its paces.
“… the 1st AI accelerator we’ve encountered for which both the hardware and the software just works … exceptionally easy to use while providing good performance and consuming little power.”
“It’s a low-power, high-efficiency workhorse … it integrates seamlessly into existing systems — bringing massive AI capability without the usual hardware overhaul.”
“When it comes to edge AI, the MX3 M.2 AI Accelerator Module punches way above its weight — literally.”
“I tested a lot of NPU accelerators. And in my opinion this one [MemryX] is the most convenient one.”
“When compared to other AI flows, MemryX finished the crossing line in first place …”
The evolution of the core technology — scaling AI compute from millions to billions of parameters.

Founded 2019 in Ann Arbor, Michigan. Built by people from Nvidia, Onsemi, IBM and the University of Michigan.


Talk to our team, or start today in the Developer Hub — the full toolchain is a free, ungated download.
Cascade modules ship through our distribution partners. Pick the channel that suits your region and order volume.